After experimenting for a few weeks with github, have decided to make a switch. This blog moves to qzaidi.github.com
You will see fewer posts here, and more of them on qzaidi.github.com.
Sunday, October 16, 2011


Thursday, April 07, 2011
Google Encrypted - killing the competition, one step at a time
Today, when I opened google search, it redirected me to a new URL
https://encrypted.google.com/
At the face of it, its an innocuous attempt by google, seemingly a very well intentioned one that provides end to end privacy for search users. But Google no longer looks like a company whose motto is 'Do No Evil' (Ref: Wifi Gate, Google Buzz), so I take this with a pinch of salt.
I think the real intent here is to make sure that Referrer data is not passed along when you click on a search result. For the technically challenged, the REFERER header is an HTTP header sent to the server when requesting a resource, that tells who referred this client. When you click on a search result and go to foobar.com, foobar.com will get a REFERER header that would be google. With the move to SSL, this would not happen anymore, so foobar.com can't tell how many users landed when searching on google. Why would that happen? Because the protocol doesn't allows secure pages to pass REFERER information to insecure pages, and most pages on any search result page would be insecure.
This is not the first time Google has tried to prevent information flow via the REFERER header. Why is this important? When you search on google and then click on a site, that site gets access to the REFERER header, which lets them know you are coming from google, and also provides information on which search terms brought you to their site. The content publisher then knows what percentage of organic search traffic they are getting, and what keywords are important. There are a host of site analytics tools that use REFERER for this reason. But that's not all. Any scripts running on the publisher page will also have this information, and ad networks can use this to build visitor profiles, do keyword targeting for search engine users, and what not.
Bottom line - a lot of third parties benefiting from the presence of the REFERER header stand to lose, and lose a lot. The last time google did something like this (they removed search terms from the REFERER), it generated such a hue and cry and they had to rollback. This time, they will be doing it quitely, and they will get away in the name of Privacy.
I am not arguing in the favor of Behavioral ad networks using that data in the name of relevance and targeting, but a case can be made for site owners and site analytics companies such as omniture. If google itself was not a player in the online advertising industry, I would still have taken them at their word. This change, however, ensures that only Google has access to the search terms, only Google Ads can use this data for targeting, and only Google AdSense can do search analytics. I wouldn't be surprised if SSL search becomes the default pretty soon. Do you think otherwise?
https://encrypted.google.com/
At the face of it, its an innocuous attempt by google, seemingly a very well intentioned one that provides end to end privacy for search users. But Google no longer looks like a company whose motto is 'Do No Evil' (Ref: Wifi Gate, Google Buzz), so I take this with a pinch of salt.
I think the real intent here is to make sure that Referrer data is not passed along when you click on a search result. For the technically challenged, the REFERER header is an HTTP header sent to the server when requesting a resource, that tells who referred this client. When you click on a search result and go to foobar.com, foobar.com will get a REFERER header that would be google. With the move to SSL, this would not happen anymore, so foobar.com can't tell how many users landed when searching on google. Why would that happen? Because the protocol doesn't allows secure pages to pass REFERER information to insecure pages, and most pages on any search result page would be insecure.
This is not the first time Google has tried to prevent information flow via the REFERER header. Why is this important? When you search on google and then click on a site, that site gets access to the REFERER header, which lets them know you are coming from google, and also provides information on which search terms brought you to their site. The content publisher then knows what percentage of organic search traffic they are getting, and what keywords are important. There are a host of site analytics tools that use REFERER for this reason. But that's not all. Any scripts running on the publisher page will also have this information, and ad networks can use this to build visitor profiles, do keyword targeting for search engine users, and what not.
Bottom line - a lot of third parties benefiting from the presence of the REFERER header stand to lose, and lose a lot. The last time google did something like this (they removed search terms from the REFERER), it generated such a hue and cry and they had to rollback. This time, they will be doing it quitely, and they will get away in the name of Privacy.
I am not arguing in the favor of Behavioral ad networks using that data in the name of relevance and targeting, but a case can be made for site owners and site analytics companies such as omniture. If google itself was not a player in the online advertising industry, I would still have taken them at their word. This change, however, ensures that only Google has access to the search terms, only Google Ads can use this data for targeting, and only Google AdSense can do search analytics. I wouldn't be surprised if SSL search becomes the default pretty soon. Do you think otherwise?
Sunday, December 26, 2010

Thursday, December 09, 2010
Iran Trip
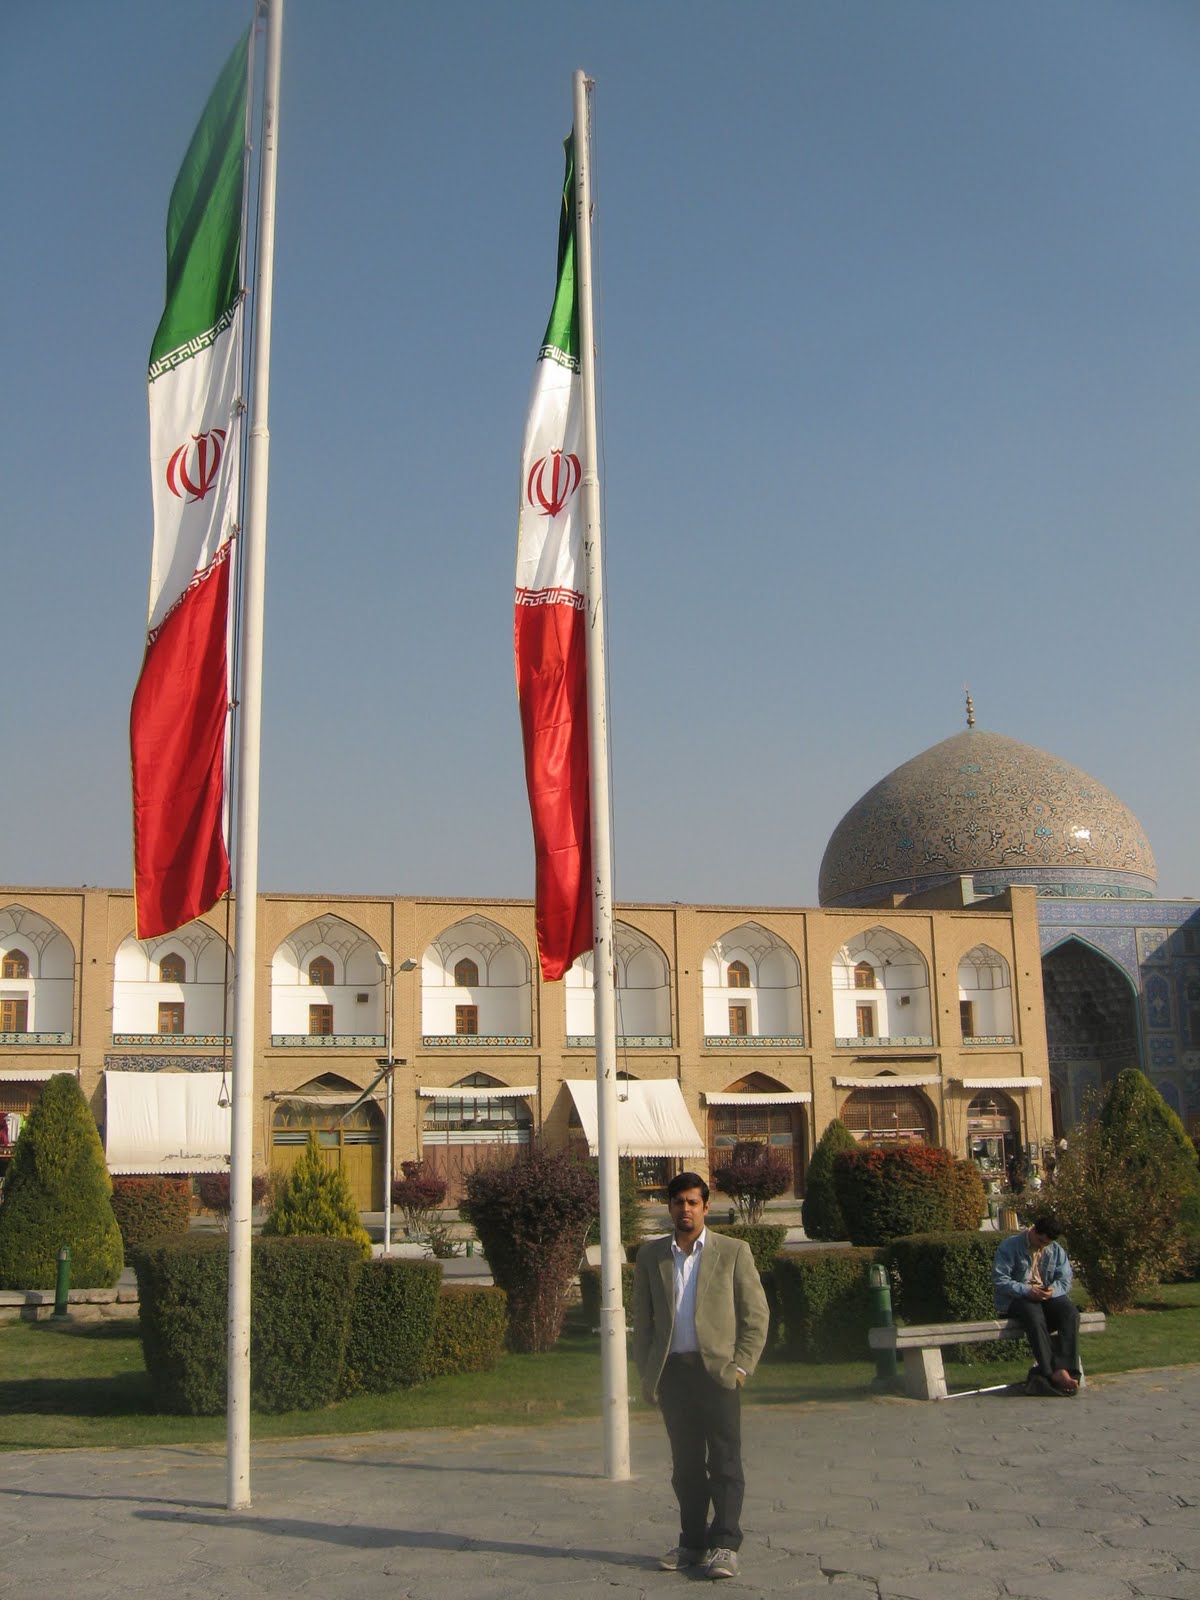
I recently undertook a trip to Iran, and it was a great experience. It would be some time before I could write up my experience and advice in a travelogue (for those who are looking to take the road less traveled), but here are some of the pics from that trip.


The entrance of the Grand Mosque in Isfahan, overlooking the Imam Square (Meidun-e-Imam), undoubtedly the best square I have ever seen. For the record, it is the second largest square in the world, beaten only by the Tiananmen Square in China.
Its also known as Naghse Jahan Square (Image of the World), and its not hard to imagine here that you have gone back in time by a century. Very peaceful, very well maintained.

And finally, I leave you with the magnificent Sio-se-pol (the 33 pillar Bridge). More if I manage to write a travelogue ...

Sunday, October 17, 2010
In The Land Of The Ayatollahs Tupac Shakur Is King
 | I found the title of this book intriguing enough to buy it. Its recommended by Lonely Planet, and I hope it would be a good read as I am planning to travel to Iran next month. |
Another related book in the same category is Nicholas Hagger's The Last Tourist In Iran. I almost ordered it for the low price, till I read the less than flattering review from Outlook Traveller. |  |
I only wish there were ebook versions that are cheaper than the price of a paperback. Right now, they are as expensive, if not more. And for all its flashy experience, nothing beats the paperback. So until we start seeing 99 cents ebooks, I will continue to buy paperbacks.
Monday, September 27, 2010
iBooks Local Language support
Why is it that all the eBook bookstores only have English books, and how long before we would see books in local languages? There is quite an opportunity there, for local language publishers.
Well, the good thing is that the epub format used on an iPad has good support for utf-8, so its quite possible to create books in Hindi/Urdu, and read them on iPad. However, the rendering of an Urdu book I created as a Proof of Concept was too slow to be of any use, and while the ePub format supports RTL (Right to Left languages), iBooks doesn't.
Without RTL support, Arabic/Urdu/Hebrew books are ruled out on iPad. Hopefully iOS4.0 would change this. As far as the rendering goes, I had all the content in a single file, so I suppose breaking it down into multiple files might have helped.
If anyone is interested, I used an online service to generate the epub from an html (although Calibre will work equally well). Then I expanded the generated epub file using zip, and edited a few things (including the RTL styling for text, so pages are turned from left to right), and compressed it back to ePub. It didn't work, but at the end of the day, its good to know ePub is only a zip file compressed with a few special options.
Saturday, September 25, 2010
What the phone companies don't want you to know
Every few years, what was once an augmented product would become a commodity. And then, manufactures must look for the next new feature, that could help them sell.
Take the case of cell phones. When mobility was no longer novel, they were being sold on grayscale displays and slimness. Then came color, camera, mp3 playback, video recording, touch screens, not necessarily in that order. Guess what - all of that has been commoditized. (Except for the touch screen, where more can still be done, not on hardware, but on interface).
So one thing that phone's are still being sold on and one feature that has not yet been milked to its full potential is positioning (or GPS). You could argue that GPS has been around for quite some time now, but I would counter argue that the phone GPS is yet to become a tom-tom replacement, in ways that most phone's have mp3 players that could replace iPods. More so in India. Location bases services are still in infancy, and except for one or two cases, turn by turn directions are still not available.
So even as cell phone companies try to extract their piece of flesh from early adopters of GPS, and the iPad version with GPS sells for an extra $129, the fact that you can add a bluetooth GPS to your phone(s), iPad(s) and other devices with only $25 in hardware cost is hidden in obscurity.
With a $25 Bluetooth GPS receiver, you get better positioning, because external GPS works better than the internal ones, which have to be cramped to fit in a phone, and which must be made to work on low power. You get improved battery life. You can use them for multiple devices, as the need may be. And you don't lose on Mobility, because they are small enough, and you are anyway going to put them in your car.
But wait a second, not so easily. Phone companies would do everything to prevent you from doing this. So Google would go to the extent of removing bluetooth support from their Maps software, as if it was never there, and Apple would cripple its own bluetooth profile to stop you from using a bluetooth GPS. Same with Android.
But there is hope. You can jailbreak the Apple iPad/iPhone, and run a $5 app from Cydia (BT-GPS). You can run Bluetooth Mouse on Android. And you can revert from the latest version of Google Maps to version 3.2, the last version with Bluetooth GPS support. And in doing so, save yourself a lot of cash. Trust me - I have learnt this after paying a lot of premium for being an early adopter.
We need Free Software for our phones and tablets, not cripple ware. Is FSF listening?
Saturday, July 31, 2010
Hello Droid!
I recently bought an android based internet tablet. Its really cheap, and inferior to iPad in all aspects (slower processor, less ram, capacitative touch screen, less memory, smaller real estate to list a few). Yet, it is considerably more open than iPad.
Apple has never been known for openness, but the extent to which they have locked down iPad is frustrating. It was frustrating with iPhone, yet iPhone’s frame of reference was other phones, and they are not open either. On the other hand, I compare my iPad to a netbook, and not being able do anything beyond apple's imagination of what people should do with there iPads is very disheartening.
Maybe the lock down is a great idea - my parents love the device for its simplicity. But for the rest of us who feel a little bit less intimidated with computers, not so. So if you have not jailbroken your iPad, craiglisting would not be a surprise to me. There's an app for everything, but there is only so much you can do.
Back to my new tablet. Its a 7 inch SmartQ v7, running a 600 MHz processor. Its capable of triple booting, and comes pre-installed with Windows CE, Linux and Android. Android looks very promising - I am still awaiting my SD card to ship, but looks like there are a lot of things I can do with it. Things like installing a 3G modem, connecting it to other USB devices, and so on. Because it runs Ubuntu too - the possibilities are endless, although by far, android is the most usable system on it.
Apple has never been known for openness, but the extent to which they have locked down iPad is frustrating. It was frustrating with iPhone, yet iPhone’s frame of reference was other phones, and they are not open either. On the other hand, I compare my iPad to a netbook, and not being able do anything beyond apple's imagination of what people should do with there iPads is very disheartening.
Maybe the lock down is a great idea - my parents love the device for its simplicity. But for the rest of us who feel a little bit less intimidated with computers, not so. So if you have not jailbroken your iPad, craiglisting would not be a surprise to me. There's an app for everything, but there is only so much you can do.
Back to my new tablet. Its a 7 inch SmartQ v7, running a 600 MHz processor. Its capable of triple booting, and comes pre-installed with Windows CE, Linux and Android. Android looks very promising - I am still awaiting my SD card to ship, but looks like there are a lot of things I can do with it. Things like installing a 3G modem, connecting it to other USB devices, and so on. Because it runs Ubuntu too - the possibilities are endless, although by far, android is the most usable system on it.
Saturday, July 03, 2010
A wallpaper a day on iPad
Guardian Eyewitness is such a great app on iPad, and I wish it had a feature allowing you to set the images as a wallpaper for that day. Being able to rotate wallpapers would be even better. Unfortunately, it won't let us do that, at least not in the current version.
However, if you have a jailbroken iPad, it should be easy to do this. First, you need to know the location of the wallpaper, which is
/User/Library/HomeBackground.jpg
Then, you need to find out the location where Eyewitness app stores the Photos. For my ipad, it is
/User/Applications/7C322A28-737A-48DC-8535-08878D6001ED/Library/Application\ Support/Eyewitness/Photos/
I don't know how the cryptic names like 7C322A28-737A-48DC-8535-08878D6001ED are derived, and I found it out using trial and error, but I believe tools like iFile have a setting in their plist that allow you to see both the encoded name and the actual app name.
For now, I just overwrote HomeBackground.jpg with one of the photos in this app, and respringed. It should be possible to write a script that runs once in a while in background, and automatically rotates between available pictures. Let's see when I have a relatively free weekend to try this out - back to work for now.
However, if you have a jailbroken iPad, it should be easy to do this. First, you need to know the location of the wallpaper, which is
/User/Library/HomeBackground.jpg
Then, you need to find out the location where Eyewitness app stores the Photos. For my ipad, it is
/User/Applications/7C322A28-737A-48DC-8535-08878D6001ED/Library/Application\ Support/Eyewitness/Photos/
I don't know how the cryptic names like 7C322A28-737A-48DC-8535-08878D6001ED are derived, and I found it out using trial and error, but I believe tools like iFile have a setting in their plist that allow you to see both the encoded name and the actual app name.
For now, I just overwrote HomeBackground.jpg with one of the photos in this app, and respringed. It should be possible to write a script that runs once in a while in background, and automatically rotates between available pictures. Let's see when I have a relatively free weekend to try this out - back to work for now.
Monday, June 07, 2010
dtrace - malloc profiling
Dtrace has been around for long, but due to some restrictions on our solaris zones, I was able to try it out only recently. And what's the verdict? I have been using a lot of debuggers, memory leak analyzers and a few profilers too - and have considerable experience with them. And I have to admit, dtrace turns out to be more impressive than I would have imaginged, and this is just the tip of an iceberg.
For a start - this is what I use to look at all the different paths calling malloc. When you have optimized your program for everything else, you may find malloc to be a big bottleneck, because it uses global locks and can slow down multi-threaded programs considerably. And you would never know of all the paths within your code or in the libraries that you use which may be making malloc calls and holding you back from unleashing the true potential. While mtmalloc can be a solution (its a multithreaded malloc library that offers decent speedup at the cost of extra memory - in one of my tests it decreased startup time from 30 seconds to 20 with a 4GB increase in used memory (from 12G to 16G), which is not bad.
However, premature optimization is the root of all evil. So before you make that call to switch to mtmalloc, just look up the paths that are frequently invoking malloc. The following dtrace one liner will print a trace listing stack dumps and their frequencies for all the calls to malloc.
Make sure to replace program above with whatever program you are debugging.
Not just this, with a simple dtrace script, you could also look at all the malloc and free calls and then do some kind of memory leak analysis on the logs. I used this script to identify some leaks, and some inefficient memory management in my program.
Run it as
dtrace -s malloc.d -p `pgrep program` and make sure you redirect stdout.
For a start - this is what I use to look at all the different paths calling malloc. When you have optimized your program for everything else, you may find malloc to be a big bottleneck, because it uses global locks and can slow down multi-threaded programs considerably. And you would never know of all the paths within your code or in the libraries that you use which may be making malloc calls and holding you back from unleashing the true potential. While mtmalloc can be a solution (its a multithreaded malloc library that offers decent speedup at the cost of extra memory - in one of my tests it decreased startup time from 30 seconds to 20 with a 4GB increase in used memory (from 12G to 16G), which is not bad.
However, premature optimization is the root of all evil. So before you make that call to switch to mtmalloc, just look up the paths that are frequently invoking malloc. The following dtrace one liner will print a trace listing stack dumps and their frequencies for all the calls to malloc.
dtrace -n 'pid$target:libc:malloc:return { @[ustack()] = count(); }' -p `pgrep -n program`
Make sure to replace program above with whatever program you are debugging.
Not just this, with a simple dtrace script, you could also look at all the malloc and free calls and then do some kind of memory leak analysis on the logs. I used this script to identify some leaks, and some inefficient memory management in my program.
#!/usr/sbin/dtrace -s
pid$target:libc:malloc:entry
{
ustack();
}
pid$target:libc:malloc:return
{
printf("%s: %x\n", probefunc, arg1);
}
pid$target:libc:free:entry
{
printf("%s: %x\n", probefunc, arg0);
}
Run it as
dtrace -s malloc.d -p `pgrep program` and make sure you redirect stdout.
Sunday, May 30, 2010
google ipad call
Using the truphone app on ipad, you can make and receive voice calls, even with the wifi version, which is what I have. The call rates are reasonably cheap, and voice quality is excellent. However, it gets better than this. You can use Google voice + Gizmo + Truphone to make free phone calls to anyone in the US, right from the iPad. Of course you need a wifi connection, but isn't this cool?
Here is how to do it
1. Sign for a truphone account, and install their iPad app.
2. Sign up for gizmo and set it up to forward it to truphone sip account (username@truphone.com). The glitch here is that since google's acquisition of gizmo, new signups have been disabled. I was lucky to have an old account lying around.
3. Signup/ signin to google voice and set it up to forward it to gizmo number
4. Go to google voice page in browser. From the bottom link, select the desktop version, as there is an issue with the mobile version which opens up automatically.
4. Make that call, choosing to let google voice connect you using the gizmo number.
That was how you make outgoing calls. Here's how to make incoming calls.
Now while truphone app is good enough, it is still not supporting push, which means you get your calls from google voice only if truphone is running in the foreground. If you have jail broken your phone using spirit, you can install backgrounder and run the truphone app in the background, which would enable you to get the calls all the time, as long as your wifi connection Is up ( or if you are on 3G already)
Here is how to do it
1. Sign for a truphone account, and install their iPad app.
2. Sign up for gizmo and set it up to forward it to truphone sip account (username@truphone.com). The glitch here is that since google's acquisition of gizmo, new signups have been disabled. I was lucky to have an old account lying around.
3. Signup/ signin to google voice and set it up to forward it to gizmo number
4. Go to google voice page in browser. From the bottom link, select the desktop version, as there is an issue with the mobile version which opens up automatically.
4. Make that call, choosing to let google voice connect you using the gizmo number.
That was how you make outgoing calls. Here's how to make incoming calls.
Now while truphone app is good enough, it is still not supporting push, which means you get your calls from google voice only if truphone is running in the foreground. If you have jail broken your phone using spirit, you can install backgrounder and run the truphone app in the background, which would enable you to get the calls all the time, as long as your wifi connection Is up ( or if you are on 3G already)
Saturday, May 08, 2010
IDN's are here
The English language has 26 letters, which when combined, produce an awful lot of words, and an even greater variety of phrases.Yet, we are running of cool domain names. Forget english words and phrases, even invented words that are catchy and easy to pronounce are in short supply.
Having missed on the first gold rush, I thought the IDNs may be an opportunity to get the kind of domain names I have always wished for. Short for Internationalized Domain names, IDN's are essentially non latin domain names. The first fully IDN domain names made their debut yesterday. This is several months after an article in one of the mainstream Indian dailies recently about Hindi domain names finally making their debut. And yes, Hindi has lost out because of proedural delays, so the first ones are in Arabic.
However, it was quite a surprise for me to know that the non english domain names have really been available since 2001. What is really new is the approval of non english extensions (so you could have the localized version of .com, .net, .tv), but sites like हिन्दीडोमेननाम.com have been around for quite sometime. A lot of issues need to be sorted. For example- how to make sure you get your email with a domain name that looks like line noise to legacy email servers? Nevertheless, I find it pretty surprising that the browsers can handle Hindi and Arabic domain names.
So here is a link to the first among equals http://موقع.وزارة-الأتصالات.مصر/. From my broken reading of Arabic, this is the website for Ministry of Communications & Information Technology, Egypt. (At first look, I translated this as Ministry of Publications and Technical Information).
Having missed on the first gold rush, I thought the IDNs may be an opportunity to get the kind of domain names I have always wished for. Short for Internationalized Domain names, IDN's are essentially non latin domain names. The first fully IDN domain names made their debut yesterday. This is several months after an article in one of the mainstream Indian dailies recently about Hindi domain names finally making their debut. And yes, Hindi has lost out because of proedural delays, so the first ones are in Arabic.
However, it was quite a surprise for me to know that the non english domain names have really been available since 2001. What is really new is the approval of non english extensions (so you could have the localized version of .com, .net, .tv), but sites like हिन्दीडोमेननाम.com have been around for quite sometime. A lot of issues need to be sorted. For example- how to make sure you get your email with a domain name that looks like line noise to legacy email servers? Nevertheless, I find it pretty surprising that the browsers can handle Hindi and Arabic domain names.
So here is a link to the first among equals http://موقع.وزارة-الأتصالات.مصر/. From my broken reading of Arabic, this is the website for Ministry of Communications & Information Technology, Egypt. (At first look, I translated this as Ministry of Publications and Technical Information).
Friday, April 16, 2010
Crossdomain is not Crossbrowser ...
While Safari and Chrome are pretty modern browsers that don't usually disappoint, in web programming, you can never be sure. I am talking about the way cross-domains is implemented.
In javascript, as a security feature, access to some objects is restricted based on document origin. If that was cryptic, here is a concrete example. A frame in a page can't read the location of the parent using window.top.location.href property , if the frame came from a different webserver than the parent.
That is, if you do something like this inside the iframe
location = window.top.location.href
you would get an exception in Firefox, and IE (at least the more recent versions)
Error: uncaught exception: Permission denied to get property
Location.href
Location.href
I guess that is what the RFC may have prescribed. However, the behavior in Chrome and Safari is different. (And chrome and safari both are based on Webkit, so its essentially webkit). They will not throw an exception, but instead merely return undefined.
Now this initially seems counter intuitive, but to think of it, I believe there is a reason why webkit behaves so. Let's say you have the following code
location = window.top.location.href
// do something
doSomething()
...
In firefox, the code that follows will never execute, because an exception was thrown when we accessed window.top.location.href. This will not be intuitive to a lame javascript programmer. Or so thought the makers of Webkit, who decided that it is smarter not to throw an exception and just set location to undefined, so that doSomething gets called. Which means any 'not so lame programmer' who writes this
try {
location = window.top.location.href
doSomething();
} catch {
doSomethingElse();
}
will find that their code wouldn't work as expected on Safari and Chrome.
Which is why it is important to adhere to the specs, in letter and spirit.
Saturday, April 03, 2010
Chat bot

For long, I have been toying with the idea of writing a chat bot for google and yahoo. I finally got around to doing that last weekend, and it proved to be much simpler than I had estimated. I
I connected the bot to Eliza (an AI program that simulates a therapist), and had it login as me on gtalk and talk to my friends and acquaintances in the contact list. The AI was pretty basic, but the conversations made for a very interesting reading. Not as good as the one at the top of this post though.
To all the unsuspecting victims in my contact list - I apologize. I was planning to use this as a Fools day prank, and then post the conversations here, but the novelty wore of much before the 1st of April, during the testing stage, and I dropped the idea. In any case, most of my Fools day prank have a reputation of being taken too seriously, creating unintended consequences. Most people I know in real life don't quite appreciate the kind of humor I like.
In any case, when I ever get the impulse to finish this project, I am going to modify it so that it could be used for logging in on Yahoo/MSN, and then create an AI that has a personality more like mine (and less like a therapist).
TODO: I am going to expand this post with a brief tutorial on how I did it for gtalk.
Saturday, February 27, 2010
Forget District 9 ...
 | Aliens are here, and they have a colony in Hyderabad, instead of South Africa. Some stupid real estate developer felt that now that all branding concepts for what is essentially a commodity product now are exhausted, selling alien space station homes would be a good idea. We already had eco homes, close to nature homes, golf course homes, so why not have alien space station homes? Here's the screenshot of an ad they are running on yahoo mail. http://aliensgroup.in/micro/html/SS1.php |
Friday, February 19, 2010
Shady URL
Dear Visitor,
For others, this is what I posted on buzz
http://5z8.info/mercenary_z9u8_IE-exploiter
http://5z8.info/stalin_s6c2_friendster-of-sex
If you are coming from buzz/twitter, and the URL link I posted made you click here, try www.shadyurl.com. It makes your URL looks so shady, people can't resist clicking. Your visit itself may be a testimony to it.
http://5z8.info/mercenary_z9u8_IE-exploiter
Even my shameless streak of self promotion didn't allow me to post the other one,
but I believe it would have got much more traffic had I posted it
http://5z8.info/stalin_s6c2_friendster-of-sex
Saturday, February 13, 2010
What is in the heap?
How to find out what is there in a process heap? Here is some Solaris fu that I found handy from a usenet post from Jonathan Adams (netbsd archives)
Let's say you have a core dump already. If you don't have it, you can always get one using gcore.
Run pmap on the core file. Look at the segment of interest. It would show you the a lot of information, starting with address, permissions, heap/stack or the name of the file that is mapped (in case of dynamically loaded libraries, for example). Once you have identified the segment of interest (which was a segment whose size was too big, in my case), use it address and get the program header using elfdump.
elfdump -p core | ggrep -iB1 -A4 FFFFFFFF7DA00000
Program Header[6]:
p_vaddr: 0xffffffff7da00000 p_flags: [ PF_W PF_R ]
p_paddr: 0 p_type: [ PT_LOAD ]
p_filesz: 0x10000 p_memsz: 0x10000
p_offset: 0x1840c8 p_align: 0
Now that you know the offset at which your segment is (p_offset), and the size, copy it using dd
dd if=core of=/tmp/data ibs=1 size=65536 seek=1589448
At this point, you could run strings on the segment to get some idea of what is contained in there.
Google is a sharp cookie
Google is now willing to tell you what they know about you. Visit the ad services preferences to find out what they know about you.
The cookie is in doubleclick.net domain, by the name id. It has a unix timestamp in it, which should show you how old your cookie is. They expire it after 1 year.
This is a good initiative on the part of Google, but here is the bit that's scary.
My cookie expires Jan 16, 2012, which means its barely a month old. In this period, they have been able to figure out that I am interested in Advertising and Marketing, Computer & Electronics->Programming, Software & Computer Security. Of course - their score is not 100%, but based on what I did during last month, thinking that I am interested in movies (I purchased a ticket for Avatar from AMC Entertainment) and Watches (I bought a few), they are close.
Too close for comfort. Would I opt out? No. But the average user might.
Saturday, January 30, 2010
Privacy and Relevance
There's a poll on linkedin that asks an interesting question
The best advertising I’ve seen online is:
* Popups that open up all over the place, opening new windows when I try to close them
* Ads that tell me I have won a million dollars by the virtue of being visitor number XXXXXX, or the ones that mimic a Windows alert dialog telling me my infected computer needs to be purged of its virii
* In text links that popup a window when the mouse moves over them even by mistake (or video ads that start playing for the same reason)* All of the above
No points for guessing that I am kidding. Never would anyone ask a question that honest. They asked this instead.
The best advertising I’ve seen online :
* Provides useful information and content* entertains me with video and sound* appears before a page loads* allows me to interact with the adAs a self proclaimed online advertising expert, I went ahead and choose the third option (appears before a page loads). But the 118 people who had chosen to answer begged to differ
* Ads that tell me I have won a million dollars by the virtue of being visitor number XXXXXX, or the ones that mimic a Windows alert dialog telling me my infected computer needs to be purged of its virii
* In text links that popup a window when the mouse moves over them even by mistake (or video ads that start playing for the same reason)
No points for guessing that I am kidding. Never would anyone ask a question that honest. They asked this instead.
The best advertising I’ve seen online :
* Provides useful information and content* entertains me with video and sound* appears before a page loads* allows me to interact with the adAs a self proclaimed online advertising expert, I went ahead and choose the third option (appears before a page loads). But the 118 people who had chosen to answer begged to differ
As a self proclaimed online advertising expert, I went ahead and choose the third option (appears before a page loads). But the 118 people who had chosen to answer begged to differ

Now what good I would be as an expert if my opinion was the same as the masses? Jokes apart, the results of this poll reflect our infatuation with metrics, and one unfortunate tradeoff. Surely, "You can't manage what you can't measure" makes for a great quote, and the ability to measure performance is one of the USP's of our industry, but this obsession has done us a great deal of harm. First, because going by the metrics that we commonly employ - all the tactics I presented as the options for the non existent linkedin poll at the start of this post, and which would make the most even the greatest fanboys of online advertising turn in their graves (there are no fanboys of online advertising - hence the grave example), will be counted among the best performing advertising seen online. They all enjoy a very high click through rate, appear to be more engaging than anything else for the advertiser, and generate more revenue for the publishers who run them. But more importantly, everyone seems to miss the tradeoff between privacy and relevance. In order that we target you better than we currently do, we need to know more about you, and that does require you giving up some of your privacy. We need to know what is 'useful information' - because one man's useful information can be another man's ... Okay, okay - no more cliches for you now.
So the unfortunate trade off between privacy and relevance is what we have to live with now. The better we become at being relevant, the more spooky it is going to appear to the average netizen, and the more concerned she is going to be about online advertising. And that is why I feel, with 95% confidence, that 61% of linkedin is mistaken. And that the best advertising after all is advertising that doesn't takes up our limited bandwidth, advertising that loads fast, and not the flashturbation we sometimes see. After all, we have found static gif banners performing better than flash and this could be the only rational explanation, however improbable, because that is the only explanation left after eliminating the impossible. But I would keep this for another post.
Tuesday, January 26, 2010
iPhone and advertising
iPhone has been a discontinuity in the mobile world, and one way it has changed the status quo is by making advertising on the iPhone a real possibility. There already have been acquisitions in this space (Admob, Quattro), and given's Apple interest in this segment, one would expect things would change.
Right now, Safari is the most difficult browser to work with when it comes to online advertising, simply because it turns third party cookie tracking off by default. Most advertising, as we know it is HTTP Cookie based, although there are several work arounds for Safari (Flash Cookie, Local Storage etc). This is even worse on iPhone, because the UIWebView component that allows applications to render html (via webkit), runs in a sandbox environment - meaning that cookies can't be shared between browsers and applications (and not even within applications). I believe this would change - although anyone enterprising enough should be able to work around this as well. I have a work around in mind - which will only be a thought experiment till the time I am able to test it out, but I believe if it works, it would present excellent opportunities. I wonder if the companies already in this space have figured this out - it seems like they haven't, at least from this dated blog post on User First Web.
I wrote recently about the new AdMob service that can tie advertising to iPhone App Store downloads. I was curious whether this feature was limited to ads in applications only or would apply to ads viewed in Mobile Safari.
AdMob clarified this via email recently saying, “as our iPhone app download tracking relies on unique user information, it only functions for ads shown within applications.”
AdMob clarified this via email recently saying, “as our iPhone app download tracking relies on unique user information, it only functions for ads shown within applications.”
If you happen to bump on this post, and have anything interesting to say in this matter - I would be interested.
Subscribe to:
Posts (Atom)